H3CHAL
Made with generative AI music: MiniMax-Music3 ComfyUI (local)video: MiniMax H3 ref2vaclips chained in the latentupscale: SeedVR2 7B
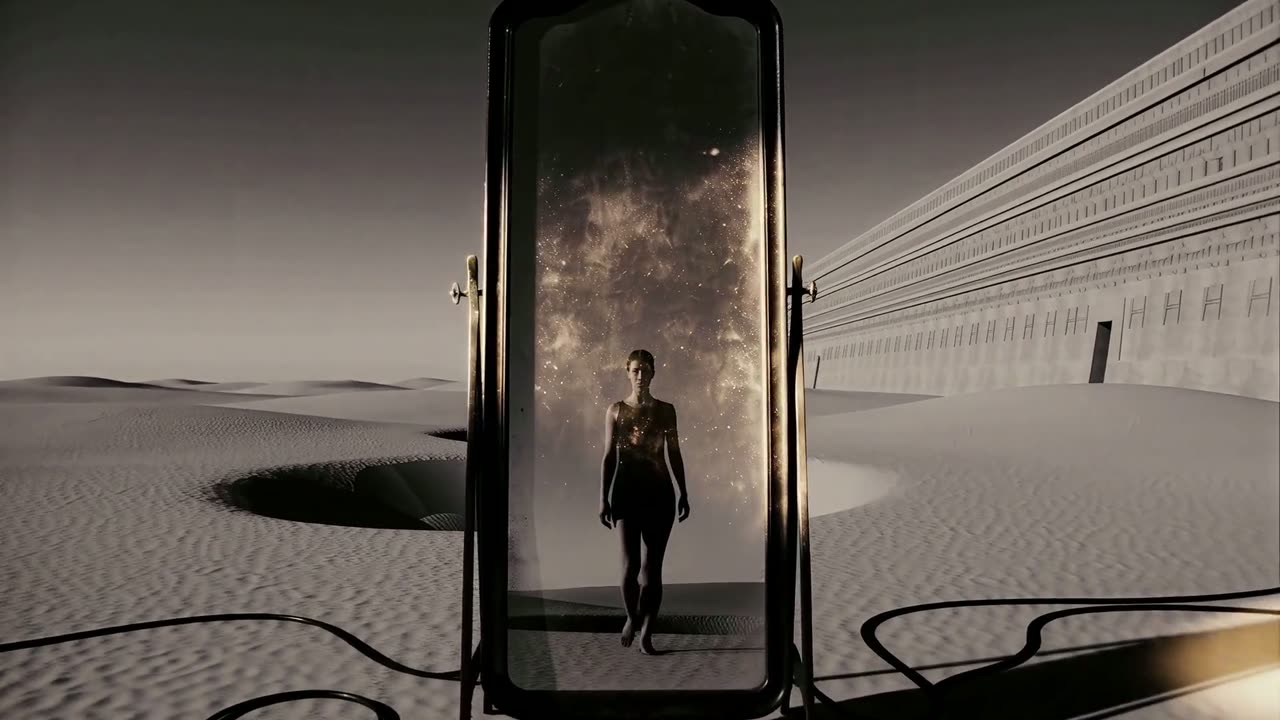
H3CHAL is a 37-second music video made for the Comfy H3 Sync Sound challenge: a dream in sepia-tinted black and white. Bare feet cross planks over a black void, pass between strangers’ legs and head down a brick alley until a desert opens up around the corner, pitted with sinkholes, with a carved stone wall across the horizon. At the end, a mirror stands in the sand. The music, from MiniMax Music 3, is a ritual piece built on drums and a drone, at about 144 BPM, with a female voice that switches languages mid-phrase.
How it was made
The images grew out of a dream of mine: a cramped noir alley, a desert around the corner, me tiny among sinkholes, and a temple carved into a mountain that spans the horizon. I described it to the Claude Code agent, and in later cuts insisted on two rules: everything seen through the dreamer’s eyes, each scene turning into the next through a crack in reality. For the song, made earlier, I wanted a female voice and lyrics with almost every word in another language.
The agent wrote the prompts (shot descriptions for the model), the lyrics and scripts, measured the audio and cut more than a dozen versions. Judging by eye and ear, I threw out an early Alice in Wonderland take that felt like a different story and one where the feet took over, and asked for a temple on a scale the mind can’t grasp.
I rendered the final cut myself in one pass of a ComfyUI music video workflow the agent had used. MiniMax H3, a video model that generates picture and sound together, builds the film there clip by clip, each picking up the previous clip’s tail in the latent, the compressed internal form the model works on. The song was in the latent too, so the picture was generated to the music. The render ran at 0.5 MP (960×544); I then halved the frame and let SeedVR2, a video upscaler that keeps new detail consistent across frames, enlarge it fourfold to 1920 pixels wide.
What it shows
- Write the song into the latent. In the working cuts, the song fed in as a plain reference came back distorted, with a different delay in each clip; I could hear the joins were off. The agent measured it and found the fix: write the song straight into the latent, masked so the model leaves it alone. In its measurements, similarity to the original (on a 0–1 scale) rose from 0.728 to 0.964.
- Resolution comes last. At 1 MP the film took almost half an hour; at 0.5 MP, 11 minutes. Ordinary upscalers treat each frame separately, so the grain flickers. In testing, SeedVR2 doubled the sharpness and kept the frame’s content.